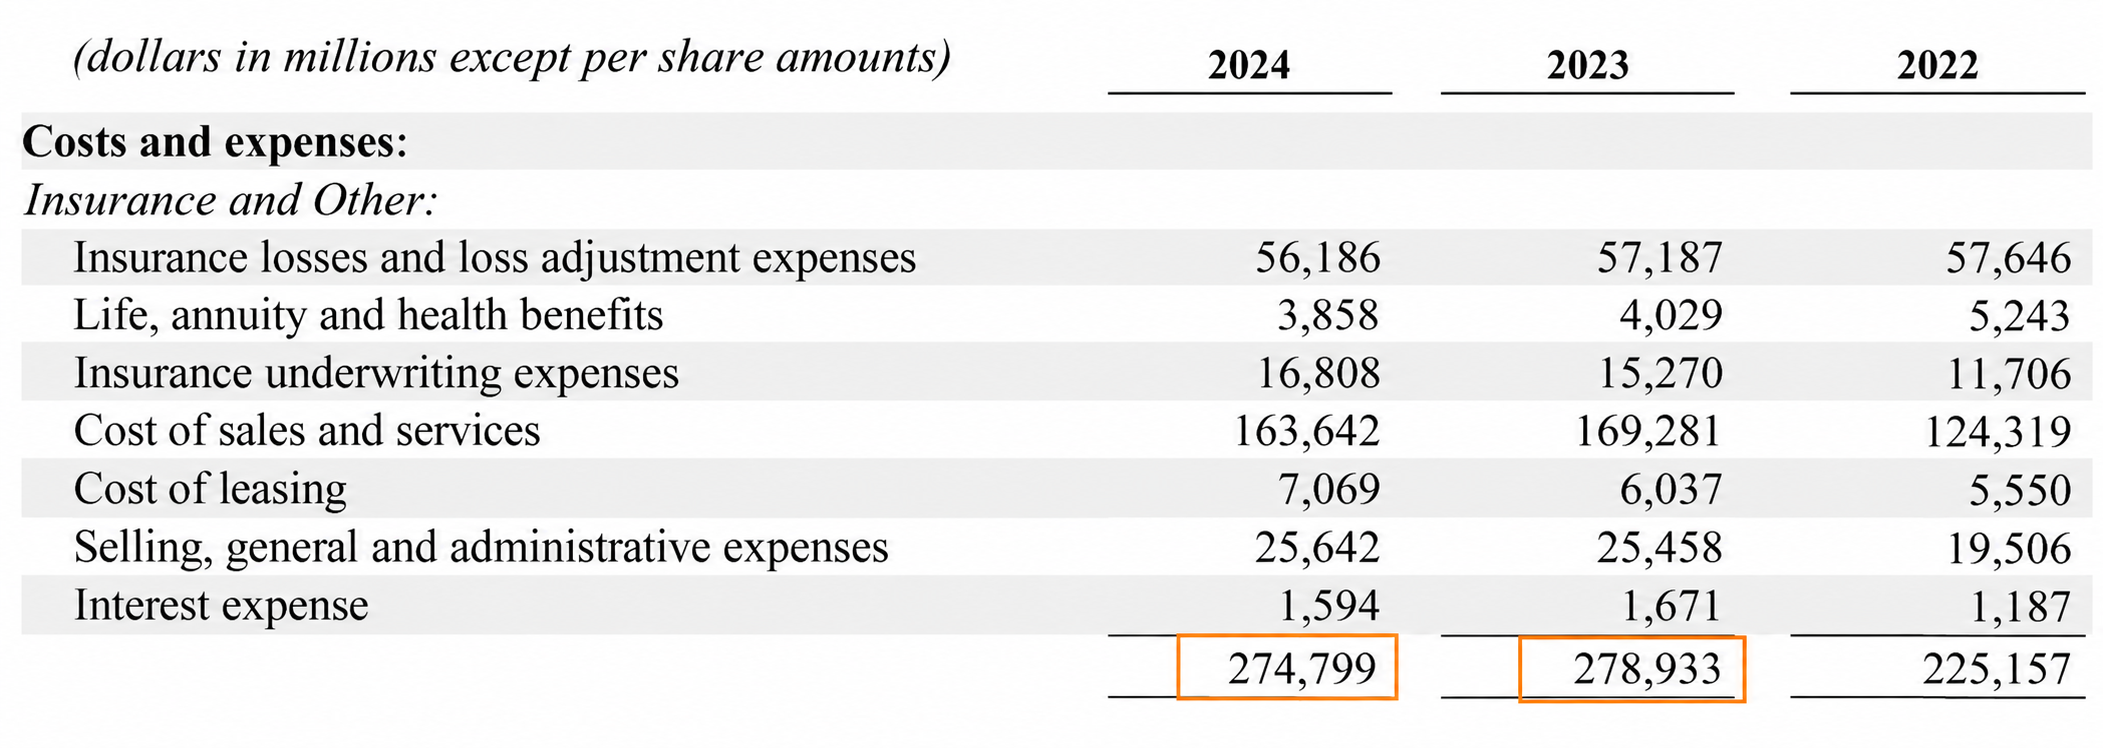Hey, Registration for PDF to Production closes tomorrow, November 13. Joe Barrow and I teach this Saturday, November 14, from 10 a.m. to 6 p.m. Eastern. It’s $500, including recordings, notebooks, $1200 of vendor credits, and 30 days of follow-up support. See the curriculum and register: https://isaacflath.com/pdf2production If you'd rather stick to free resources and piece things together yourself, check out the Document Roadmap. It goes through an overview of key misconceptions and key...
1 day ago • 1 min read
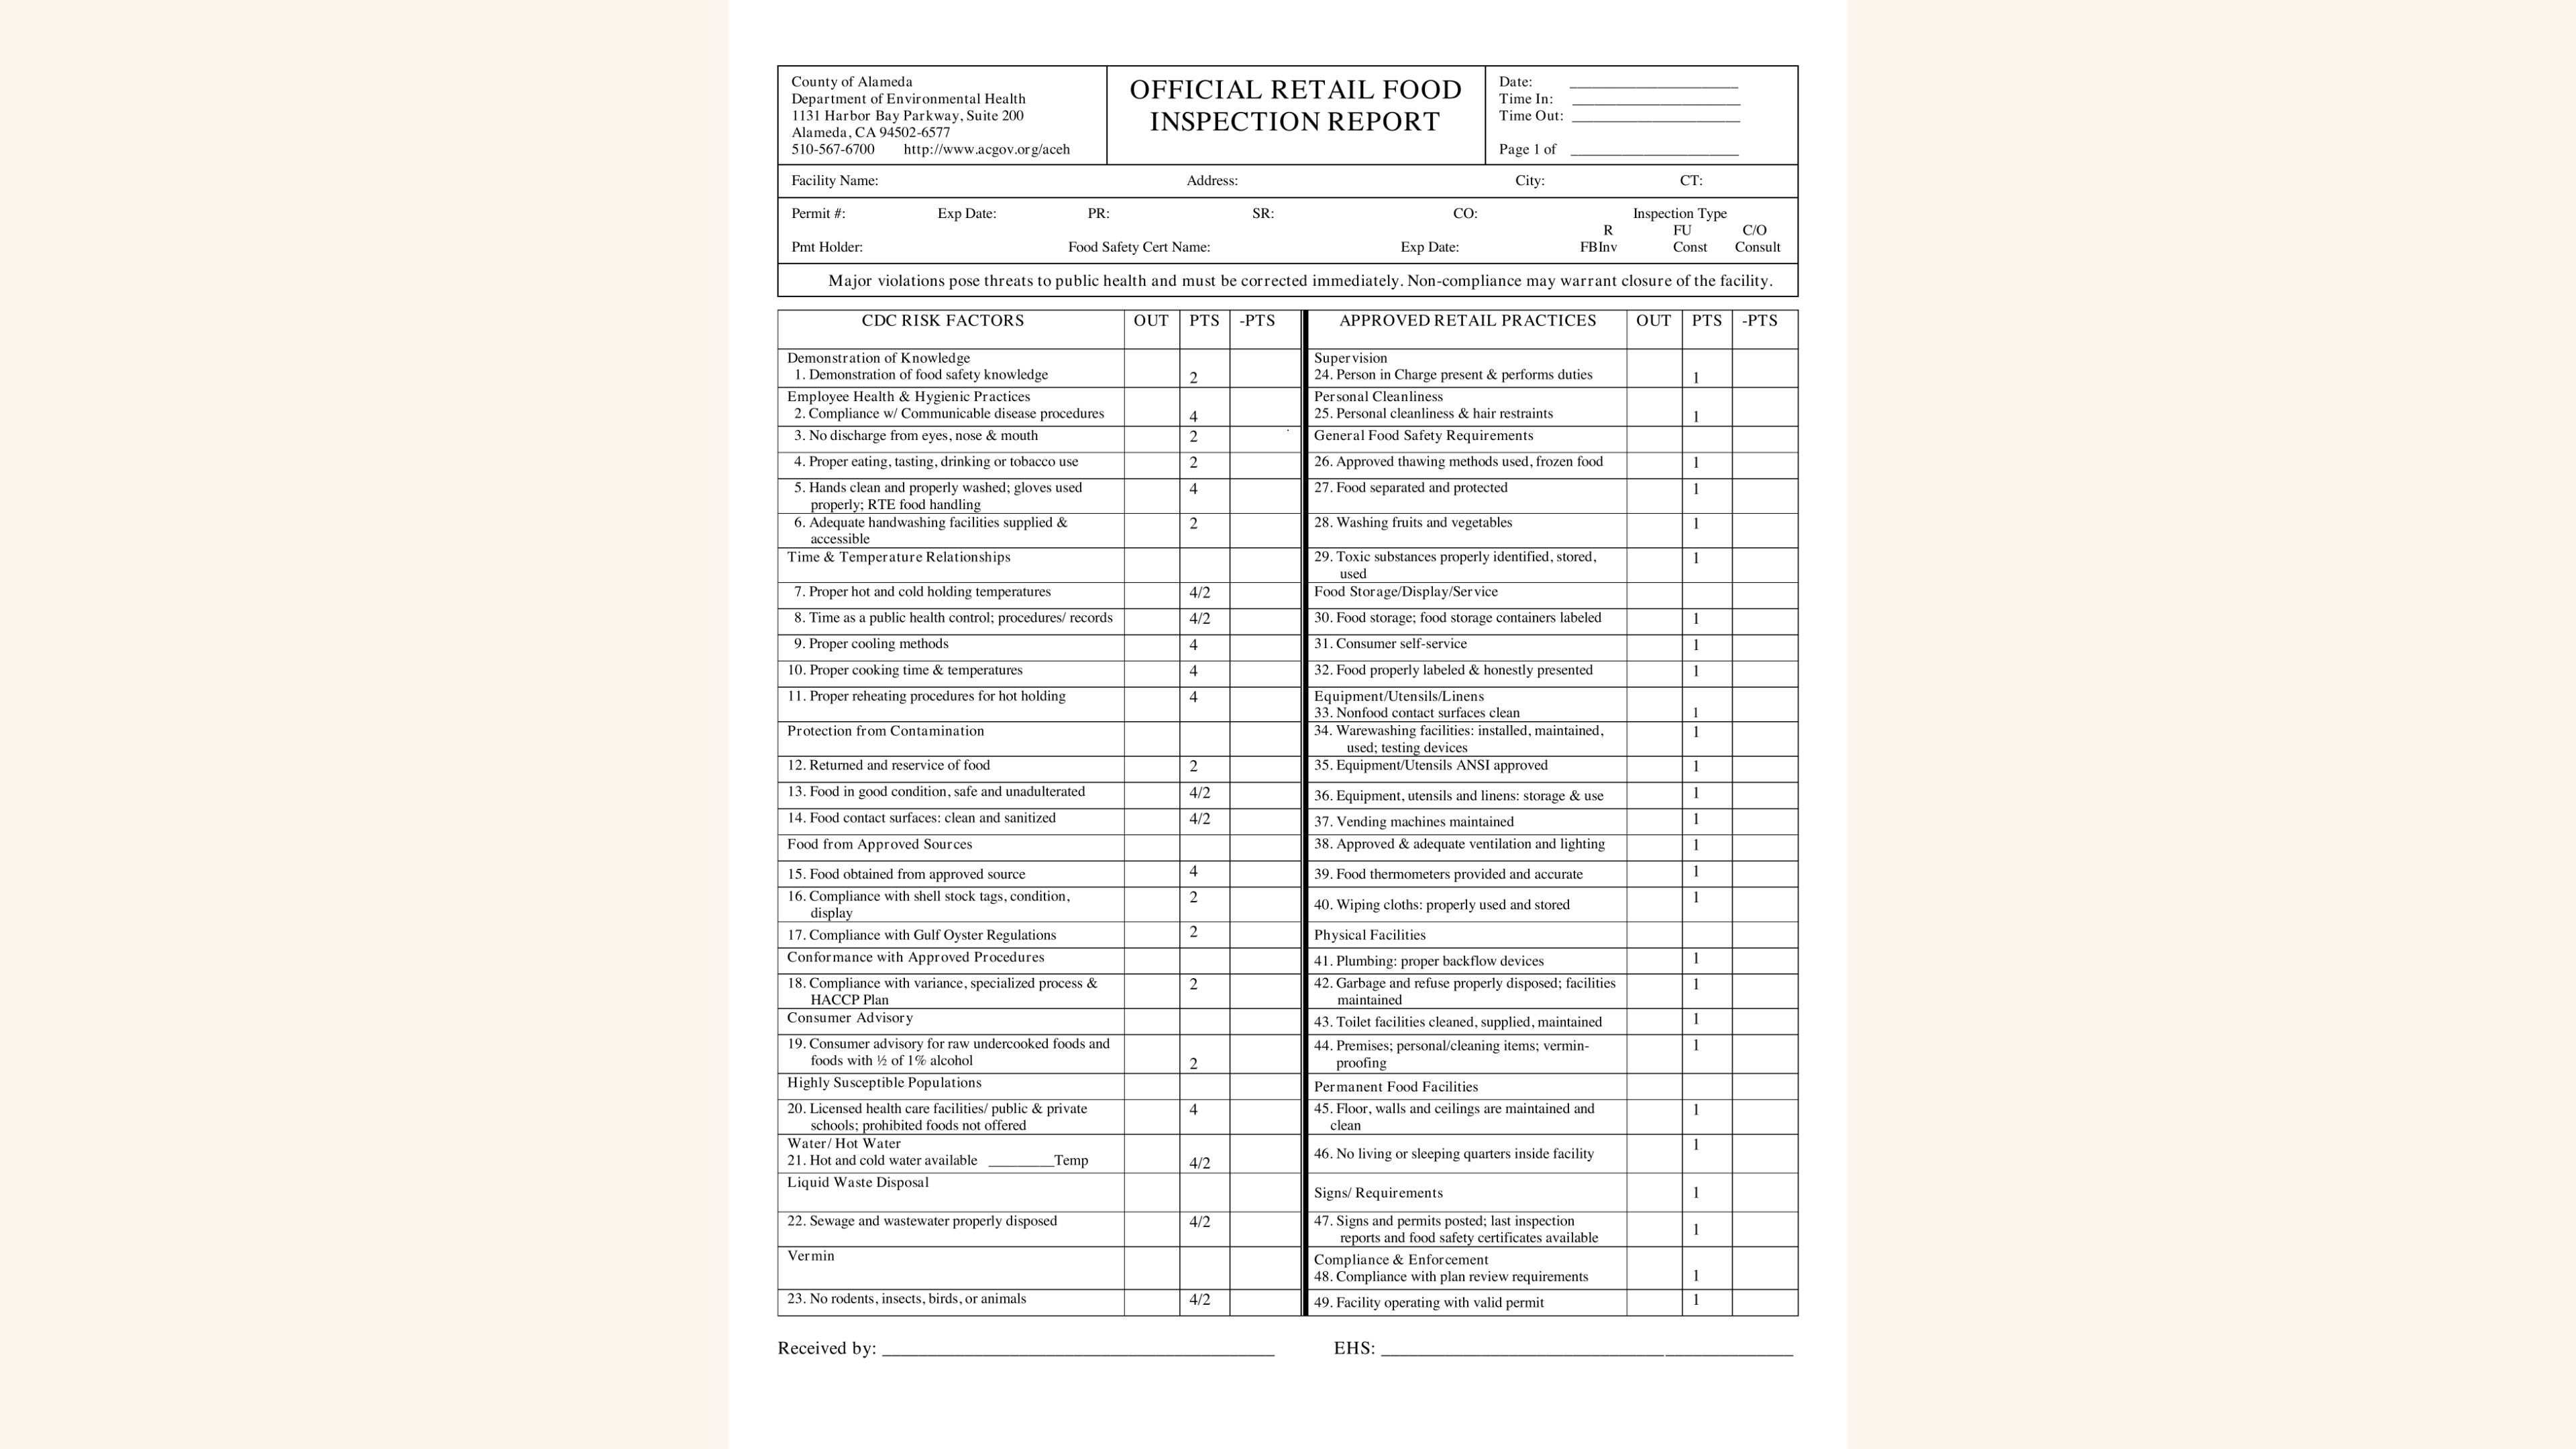
Hey, There's been a ton of valid skepticism around benchmarks recently, but there's a lot of good reason for optimism too! Joe and I are going to discuss one of those in the document space, which is how unit tests are being used in benchmarks. And all of this is applicable to your own product's evals. After all, a benchmark is just another person's evals 😅. This Wednesday, Joe and I are discussing why unit tests make strong OCR benchmarks and how to design them. We’ll work through examples...
4 days ago • 1 min read
Hey, I wanted to understand how decision models (like Jev) actually work in detail. I use them a ton, and it's clear they're going to be a key part of software moving forward. Joe and I spent an hour going through all of that, using Perplexity Decider (OSS decision model) to go through the architecture. The talk walks through how this is built: Turning a decoder model into an encoder by changing its full-attention layers. Replacing the language-modeling head with a small head that produces...
9 days ago • 1 min read
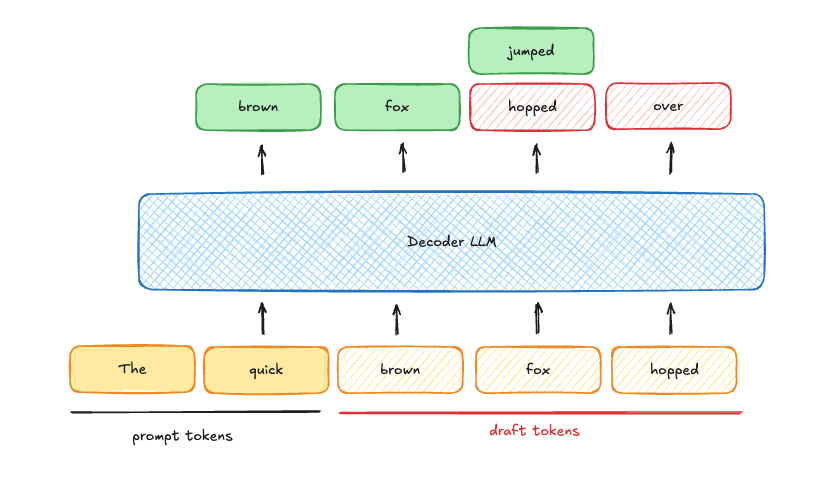
LLMs can be made faster with speculative decoding, even while doing more computation (wut???). It does this because the extra compute is spare GPU compute that would be idle while waiting for other parts of the system to finish its tasks. But this only works in specific situations (usually low batch size). It's still useful loads of the time, and you can dynamically adjust based on the situation. This Wednesday, Joe and I are giving a free talk on why this works. We’ll walk through the...
11 days ago • 1 min read
2 new free resources. First, If you've been wondering wtf a decision model actually is, join us. Joe Barrow and I are going to be going into architecture details on the top OSS decision model by Perplexity. It's a free live discussion tomorrow night, Wednesday, on Decision Models like Jev. Second, the written guide on formative and summative evals a few weeks ago was very popular, so I made an 11 minute video walkthrough going through it and all the examples (agent and OCR examples over...
17 days ago • 1 min read
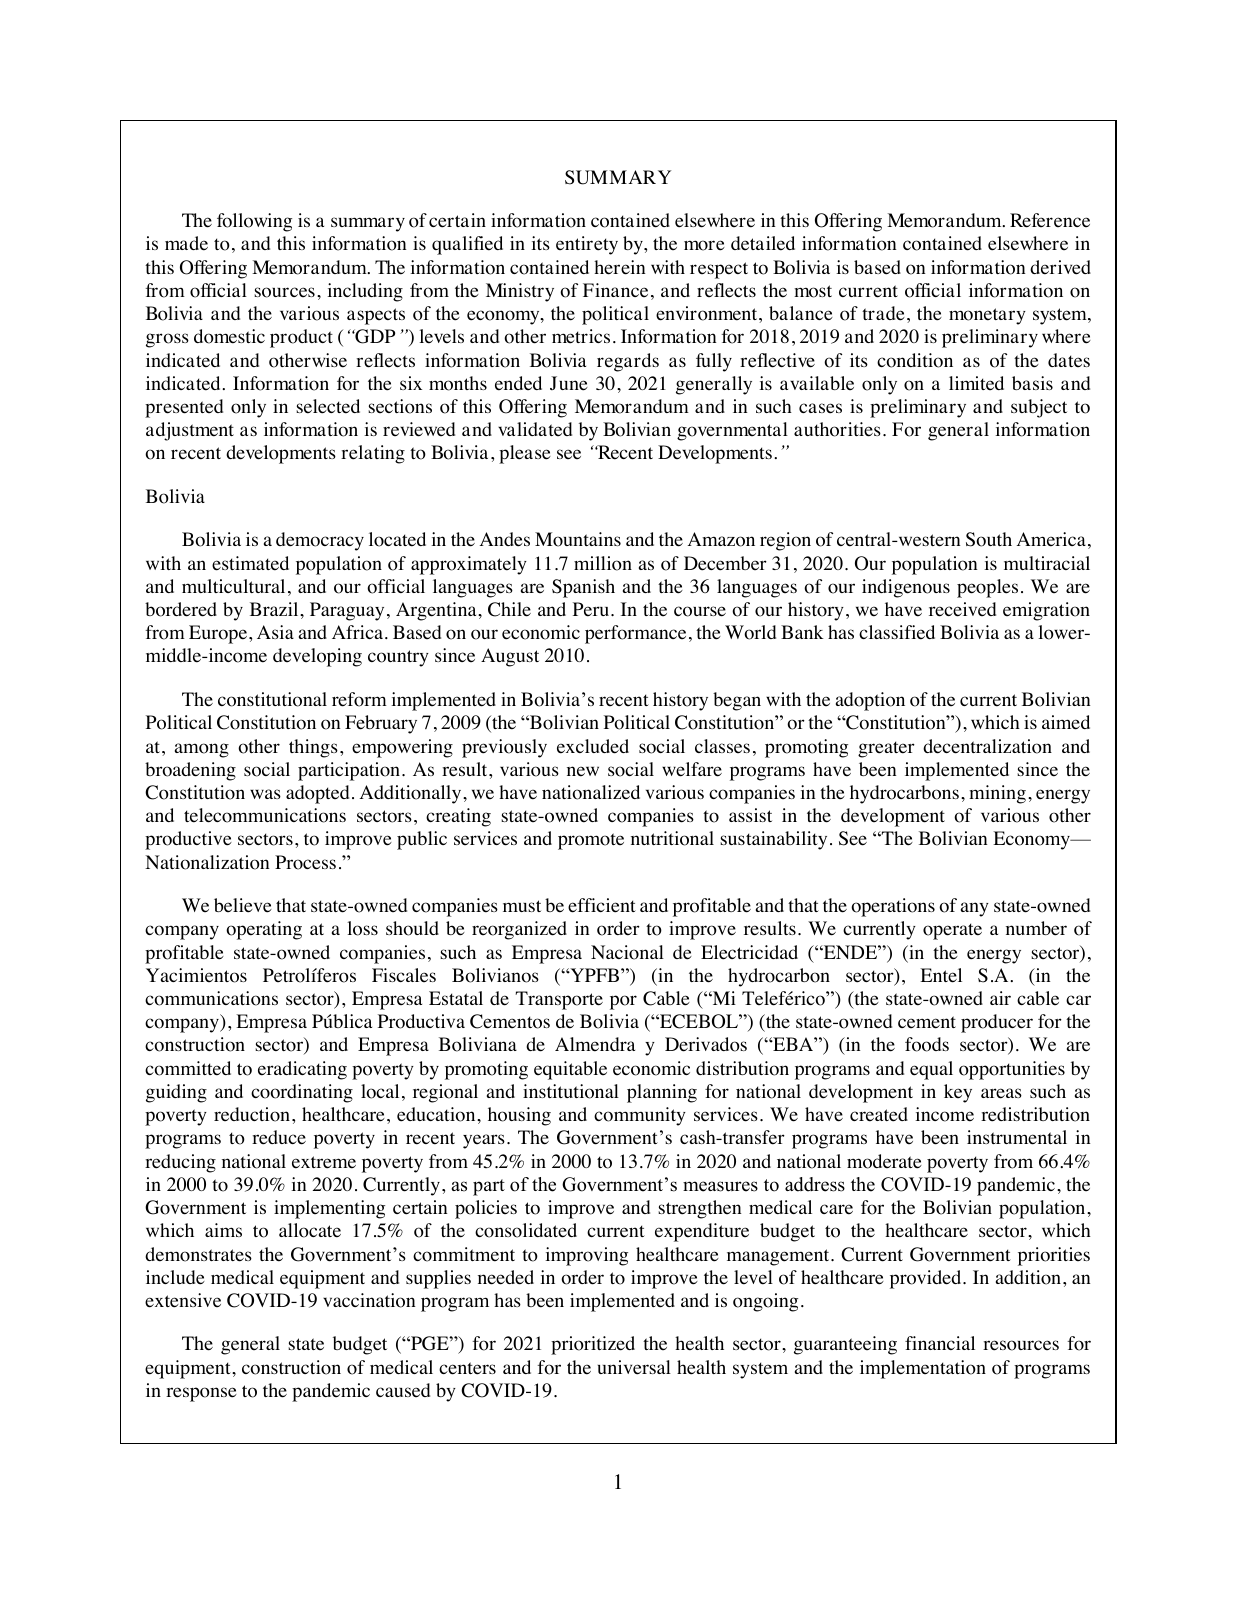
I created this walkthrough on OCR routers because everyone wants more accurate OCR for less cost (duh!). Routing to the right model per page is actually quite doable because a report often has a title page (easy) a written summary (easy) then a bunch of dense data tables, charts, images (hard). In the post & video, I start with a rule based router, then show how to do error analysis on it.how to do error analysis on routers, and look at common failure mode. We then cover how more advanced...
26 days ago • 12 min read
There's been a lot of new releases about documents. Here's the lightning version for the 5 of them (for more detail and videos go to my news feed). Also - Joe Barrow and I will be livestreaming a dive into post processing for OCR and the recent & related paper, Miner U Popo, tomorrow. Sign up here if you want a calendar invite with a link so you don't miss it. PP-DocLayoutV3: Reading Order and Warped Text Layout parsers often work sequentially (figure out block 1, then block 2, then block 3,...
about 1 month ago • 2 min read
Most people I talk to feel like they "look at their data" but when I see their process it's not what I mean when I say "look at your data". So I've been making a lot of material showing what I mean on real examples. Today's post shows two of my workflows for OCR, and agentic question answering over PDFs. There's a video and a post, but the video makes it much easier to see the workflow. But I know many of ya'll hate watching video (that used to be me too, until AI slop took over text...
about 1 month ago • 15 min read
The most common questions I get (other than "what model do I pick?") is how do I evaluate OCR? How do you know how good a model is doing on your data? When I look at my data, what do I do when I see something I don't like? Today's post is on how to do that, and how to turn (semi-painful) adhoc inspection into repeatable tests at multiple levels. Also - As a reminder, early bird pricing for the PDF to Production course ends today. Formative vs. Summative Evals for Document AI To generate...
about 1 month ago • 5 min read
I’ve been working on extracting data from documents, and I've shared a bunch to of stuff on the topic Hosted talks on OCR and VLMs to get tables, text, images, etc. out of documents Mini examples of which models and pipelines work in specific cases Retrieval on PDF documents to grab specific source data Antaripa Saha worked on #3 as part of her work in the AI Product Engineering Club. She compared keyword search, dense OCR, visual embeddings, multivectors, and reranking on complex financial...
3 months ago • 9 min read